
When GenAI was a shiny, new thing, its use was limited to a content generation engine that summarized documents and answered questions. However, Agentic AI has taken the driver’s seat today, responsible for chaining tasks, making decisions, taking autonomous actions, and interacting with APIs, databases, and external systems in real time.
While this advancement highlights exponential productivity, it creates a new failure surface. How? If AI starts to act instead of just replying to the prompts, the:
- Undetected model hallucinations can have negative repercussions by impacting simple, everyday decisions.
- A single prompt that is cleverly crafted to manipulate systems can expose confidential data.
- Non-determinism of AI systems can turn into a serious business risk in industries and workflows where objectivity is paramount.
Surprisingly, most organizations still rely on traditional testing strategies, which were designed for static, deterministic software. These methods are no longer effective for new-age, evolving systems. The need of the hour is a modern QE playbook supported by QualiZeal’s ValidAIte™ , an enterprise-grade assurance framework to measure, manage, and continuously assure AI system quality across the full lifecycle.
Fix What’s Broken: Why Traditional Testing Fails in the GenAI Era
GenAI and Agentic AI systems no longer perform according to rule-based approaches to providing outputs. Traditional QA testing approaches for validating their response increase vulnerabilities and miss critical risks such as hidden bias, unfairness, and data inaccuracies, which lead to unpredictable failures.
Here are the top three reasons why traditional testing fails in the GenAI era:
- Determinism is Dead
Determinism is the core principle of traditional software applications. When testing classic software, the results are a simple ‘yes’ or ‘no’. This method is not valid with GenAI systems, as their performance is based on how LLM models are influenced through data drifts, random sampling, and training on limited datasets. Their output varies even with the same inputs. Models can generate plausible but incorrect information. Further, with Agentic AI added to this layer, it could trigger a chain of actions, updates, and consequences, making static test cases unsuitable.
- The Black Box Problem
In traditional testing, test engineers can easily trace the logic paths from the test outputs to determine the branches and debug behavior. However, in the case of GenAI models, reverse engineering cannot be performed even when they know the complete prompt word by word. Because, the LLMs in GenAI applications consist of large neural networks with billions of parameters that cannot be directly interpreted.
- Risks are Emergent, Not Static
Testing traditional software helps uncover risks and errors, which are often fixed or static until a new release or feature change. But with GenAI, risks like prompt injection, jailbreaks, hallucinations, and RAG drift continuously evolve.
Suppose a GenAI-powered customer support system passes the UAT; however, a few weeks later, it suggests outdated or harmful policies because the RAG context source changed. This is because the QA approach used during the system’s pre-launch stage will be inadequate to understand its continuous performance under real-world conditions. Therefore, the testing must be constant and adaptive to changes.
QualiZeal’s Approach: Automation-First and AI-Native Platform-Powered
QualiZeal has been the pioneer of AI-powered Quality Engineering. Being a trusted partner for several global enterprise clients, including Fortune 500s, to achieve automated and accelerated quality assurance at every step of their digital transformation.
- Through the flagship product, ‘QMentisAI,’ an enterprise-grade Quality Lifecycle Management (QLM) platform, QualiZeal pioneers an AI-powered approach to software testing. It embeds intelligent automation combined with human insights across the testing layers to accelerate the release of high-quality products.
- QualiZeal’s comprehensive testing frameworks and test suites implement automation-first pipelines to enhance release confidence and velocity.
- To achieve seamless scalability across enterprises, QualiCentral’s industry-recognized suite of pre-built QE assets and accelerators enables a platform-powered delivery model.
QualiZeal recently introduced ValidAIte™, an advanced, purpose-built framework to transform uncertainty within AI and Agentic AI systems, making their testing and validation measurable, manageable, and compliant.
ValidAIte: A Modern QE Toolkit for AI Testing
ValidAIte’s enterprise-grade assurance framework is designed uniquely to address probabilistic models, evolving behaviors, and risks of regulatory scrutiny in AI systems by continuously improving and validating its responses. The trust-first framework is designed on four foundational pillars, each addressing a key aspect of AI validation and assurance.
1. Functional & Behavioral Validation
A regular user of the GenAI system would have observed that there is no single answer for one prompt; the system can generate several variations.
- ValidAIte™ performs multi-run harnesses to test outputs regarding variability for multiple iterations.
- The framework performs fact-grounded checks to prevent hallucinations and verify the knowledge base.
- Additionally, it performs prompt intent coverage to check outputs for different input phrasings.
Example: A user may ask the system ‘Reset my password’ and receive 100+ variations of the output. ValidAlte checks that each prompt follows the same secure flow, regardless of the phrasing.
2. Safety & Security Hardening
GenAI systems are easy prey for data leakages and prompt injections. ValidAlte helps identify these serious vulnerabilities:
- It performs a prompt injection simulation to discover vulnerabilities by simulating malicious input data.
- It introduces Jailbreak detection simulations to track whether the GenAI model bypasses the integrated restrictions.
- The framework can also perform a guardrail breach logging analysis to find possible policy violations and unexpected behaviors of the AI system before deployment.
Example: ValidAlte tests whether an agent-based HR AI accidentally displays salaries when a user prompts with social engineering inputs.
3. Continuous Quality Telemetry
Since GenAI models continuously evolve, even a slight data update risks introducing bias or drift in the outputs. Or it can create an impact on performance. ValidAlte establishes a continuous quality telemetry to track:
- Golden tasks as a fixed benchmark query for tracking long-term performance.
- Bias and fairness sampling to track ethical consistency.
- It measures KPIs such as real-time latency, throughput, and API cost tracking to monitor efficiency.
Example: A healthcare chatbot showed no signs of any issue at the launch; however, with ValidAlte’s drift monitoring, changes in the triage response quality can be discovered with every LLM update.
4. Compliance & Governance-by-Design
ValidAlte ensures compliance, building trust from the beginning to ensure explainable validation and adhering to regulatory requirements.
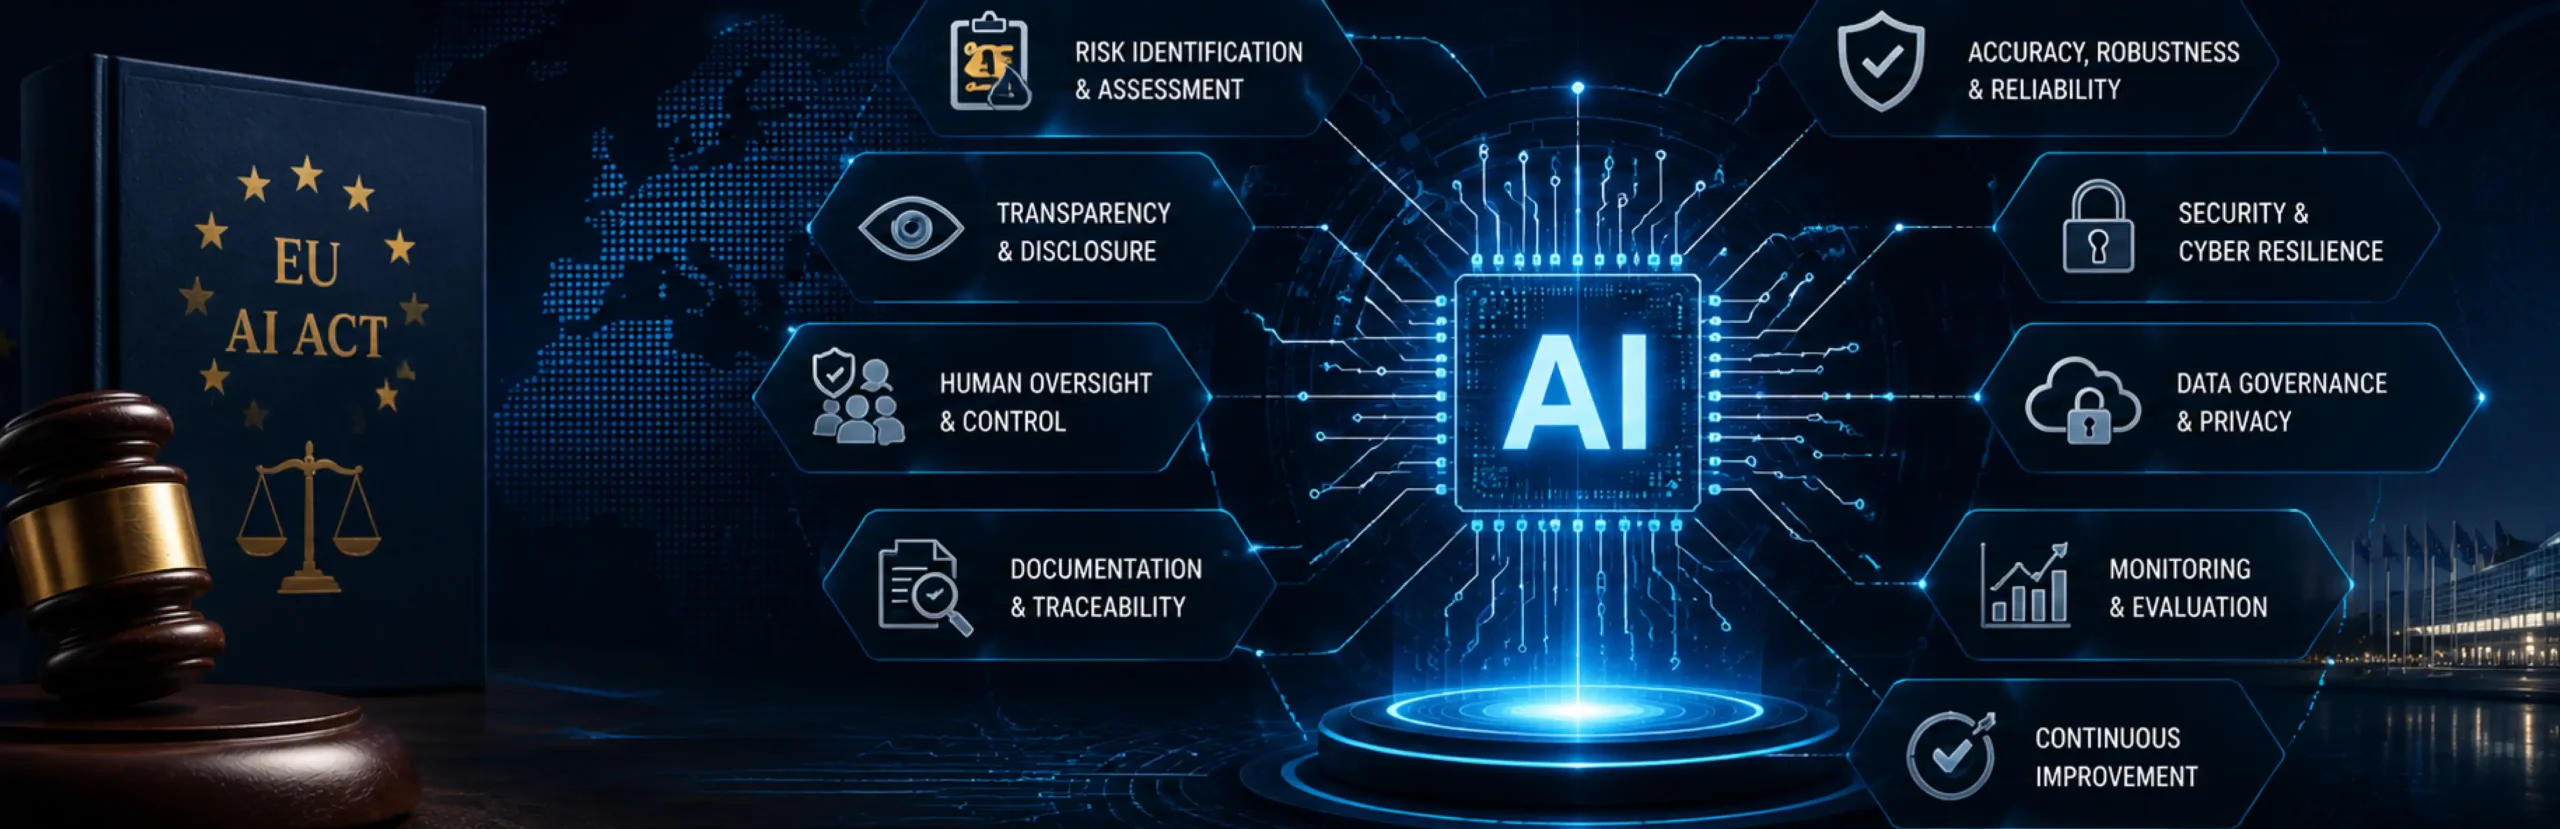
- It offers audit-ready evidence packs mapped to ISO/IEC 42001, NIST AI RMF, and EU AI Act.
- The framework ensures role-based responsibilities for ownership, quality traceability, and accountability.
Example: ValidAIte exports audit logs, enabling the AI team and relevant stakeholders to demonstrate GDPR-safe testing practices. This is especially beneficial in industries governed by the EU’s data privacy and security regulations.functional coverage. This optimization improves test efficiency without compromising quality.
The Playbook: Real-World Scenarios & Role-Based Action
For systems that behave as programmed, traditional testing methods work fine. But with GenAI systems, as the learning process is continuous, the results cannot be interpreted. Therefore, the real-world scenarios initiate the need for a new QE playbook that takes into considerations:
1. Hallucinations in Legal Systems
GenAI-powered legal assistants are commonly used by law firms and paralegals to assist with case preparations. Any fabrication or misinterpretation in the citation documents impacts the legal proceedings, resulting in reputational damage.
ValidAlte frameworks perform a multi-run fact check to validate outputs and verify data against trusted lawsuit databases, ensuring that only real and factual facts are provided in the output responses.
2. Prompt Injection in Finance
Accidental data exposure and privacy risks are common concerns in highly regulated industries like banking, financial services, and healthcare. Bad actors can easily exploit AI systems used by a finance services company by using hidden prompts masked as a support query. With prompt injections, attackers can prompt the system to leak internal calculations and critical confidential data. The consequences? Losing sensitive data or private information can result in serious compliance violations.
ValidAlte’s adversarial suites include several test inputs designed to exploit vulnerabilities in AI models by testing their resilience against model manipulations or attacks. Implementing automated prompt injection simulation helps discover vulnerabilities before AI implementation.
3. Evaluation Drift in Insurance AI
An underwriting assistant can perform efficiently at the time of deployment. It can start misclassifying risk categories due to LLM model updates from the provider. Result? Sudden drifts in the output may cause regulatory issues if they go undetected.
ValidAlte establishes golden test benchmarks to monitor drifts and AI behavior in real-world scenarios, ensuring that unknown risks are not left unidentified but become measurable signals. With its regression catalog that covers prompt-response pairs to check for consistency after model fine-tuning, the framework ensures no regressions regarding text generation quality or image synthesis.
Role-by-Role Clarity for Modern QE Teams
The framework alone can’t be solely responsible for ensuring quality. Accountability matters, so ValidAlte clearly specifies ownership across the different layers of QE.
QA Leaders: Define the strategic assurance roadmaps, align testing and compliance requirements, and build governance structures.
Architects: Design technical scaffolding, including evaluation harnesses and add prompt variation sets to track the real-world behavior of AI.
Engineers: Run behavioral, bias, and security tests, and validate output for potential vulnerabilities and performance.
SREs: Monitor drift and latency of the AI system and evaluate incident response to monitor GenAI system health.
Compliance Officers: Map and audit outputs and GenAI systems to evolving AI regulations such as the EU AI Act and NIST AI RMF.
Final Word: The Path to AI Trust with QE for AI Applications
Today, GenAI systems take over the role of decision-makers, actors, and communicators, assisting human actions with relevant outcomes and prompt responses. As their criticality deepens as an enterprise essential to navigating the evolving digitization goals, GenAI systems can also become risk amplifiers without adequate testing and responsible validation.
This marks the end of traditional QA, front-loading battle-tested assurance frameworks like ValidAIte to turn uncertainty into business confidence, regulatory readiness, and competitive advantage.
Ready to explore the next steps for a thorough GenAI system validation?
Connect with our team for a complimentary assessment and discover how the assurance framework helps bring AI projects to production while demonstrating clear business value and regulatory compliance.