Let’s say you are the Head of Quality Engineering for a division of a technology conglomerate operating in customer-facing, high-stakes industries such as banking, healthcare, and the public sector. Your company’s average turnover would be anywhere from single- to double-digit billions. When you sign off a release, how much of that confidence is backed by expertise, and how much is professional hope and optimism?
Because one bad release with a minor system glitch can balloon into breached SLAs, privacy violations, a massive drop in customer/user ratings, post-release quality forensics that diminish engineering morale, and developer burnout. QE teams already understand these repercussions. But in an AI-native age, where QE architecture can’t remain only a gatekeeping function and must evolve into continuous intelligence and risk management, human effort must be directed to the most consequential areas.
QualiZeal’s newly unveiled version of QMentisAI, the enterprise Agentic QE platform, represents a fundamental shift that helps the heads of QE, key decision-makers, and practitioners move confidently from hope to evidence. Read further to understand the platform’s capabilities, evolving from task-level AI assistance to continuous, context-aware, and governed engineering autonomy.
Why Does a Governed Agentic QE Operating Model Matter?
Recently, AI-powered testing tools, copilots, and test management systems have multiplied in availability and adoption. Your QE teams’ experience and diligence haven’t dropped, but they don’t scale or show up in processes. But the same narrative continues—manual effort spread across the QE lifecycle, quality validated too late to matter, coverage gaps that let critical defects escape, automation scripts too brittle to survive the next release.
Suppose things didn’t go as expected for the recent release; the metrics from your AI-powered or manual QE didn’t move up the value chain, where would you investigate? Instinctively, you might wonder whether you just ‘hoped’ the requirements were clear enough, coverage wide enough, and the automation smart enough to catch what manual testers missed. Below are some findings that paint a grim picture, grounding any QE leader and moving them from hope to reality.
According to research data by the IBM System Sciences Institute on software development projects, identifying a bug or error during the requirements stage costs 1X the baseline. As you move from design → coding → testing, the cost can inflate 10X. Once the defects reach production, fixing them can cost 15X to 100X the requirements baseline, depending on severity and downstream impact.
Bolting AI-powered QE onto a flawed process accelerates flawed outcomes that ultimately demand more rework, time, and cost. In 2026, with nearly two thirds of enterprise leaders placing huge bets on agentic AI, it is worth exploring autonomous reasoning within governance and human accountability, giving your team a QE architecture that builds trust for confident release.
This is where QMentisAI’s agentic platform helps by amplifying QE and simultaneously reducing toil through Autonomy, Efficiency, and Accountability
Powering Full-Lifecycle Autonomy: QMentisAI Delivers the Agentic Layer Beyond QE Tasks
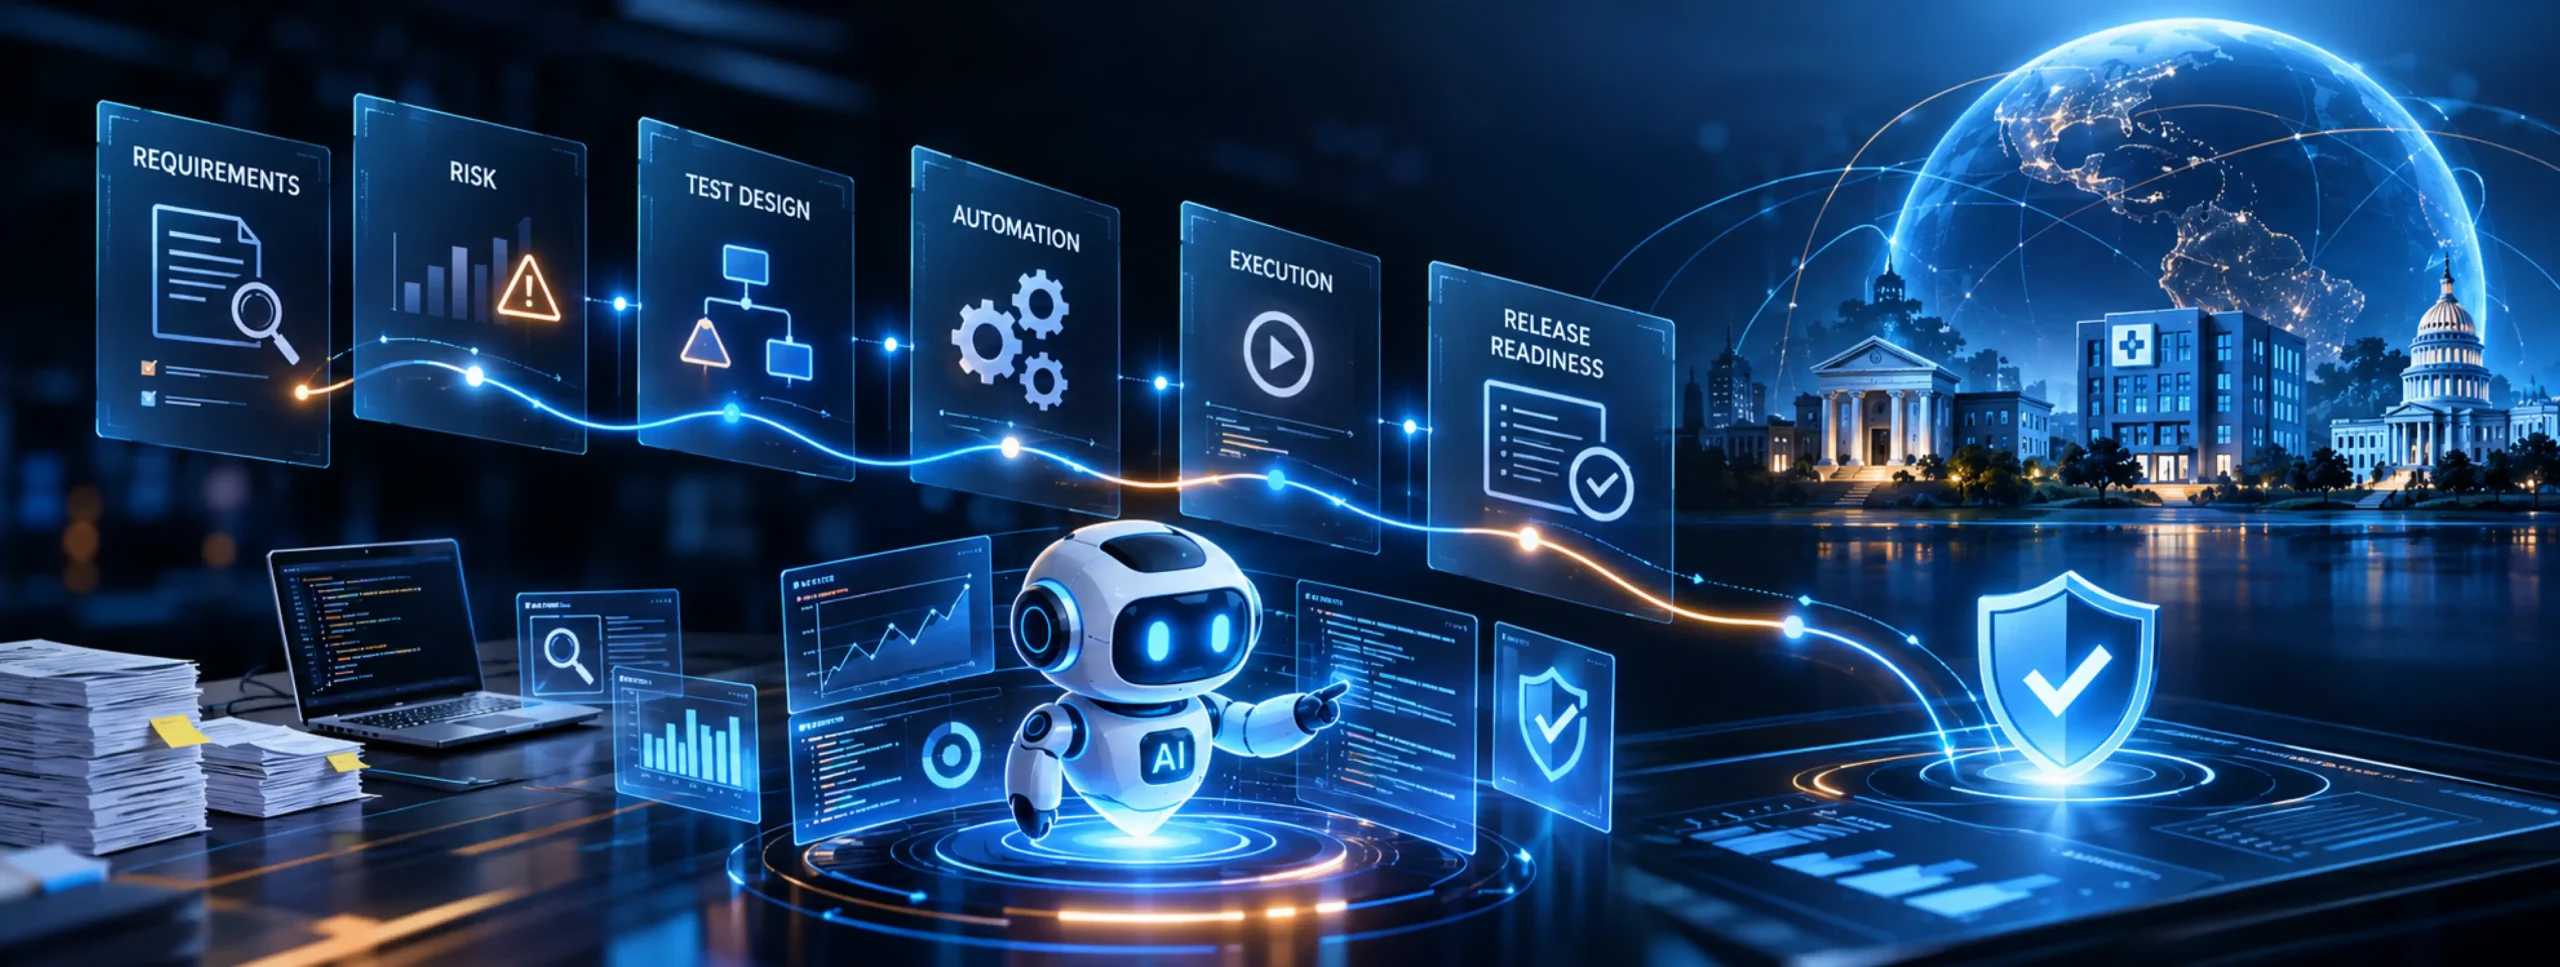
When speaking of agent autonomy, QMentisAI doesn’t just accelerate QE tasks but runs the entire QE workflow across six connected phases. It is powered by 50+ governed agents that continuously perceive the engineering, reason about risk and context before acting, execute work autonomously within governance boundaries, and escalate to a human only when judgment genuinely requires it. The platform isn’t about six tools stitched together and handed off in a sequence.
| Phase 1 | Requirement Intelligence | The agents review every new or changed requirement for ambiguity and testability even before a single line of code is written. |
| Phase 2 | Risk Assessment & Planning | The agents maintain a living risk model that translates directly into risk-differentiated test coverage and not coverage built by habit. |
| Phase 3 | Test Design | The agents generate test cases as per the team’s own depth and style standards, rather than generic output that needs iterations. |
| Phase 4 | Automation Strategy | The agents score what tests actually require automation investment, instead of automating indiscriminately. |
| Phase 5 | Execution Intelligence | The agents ingest results from existing execution infrastructure and detect patterns with real release consequences. |
| Phase 6 | Release Readiness | The agents close the loop with an evidence-driven release readiness statement on what was tested, why, and what residual risks still remain. This evidence holds even under an an audit. |
The Four-Zone Autonomy Envelope:
Before QMentisAI proceeds with any action, it asks three simple questions: how much is at stake, how complex is the task, and how confident am I in what I currently know. The response is a place into one of the four zones that decides who acts.
| Zones | Risk, Complexity, & Confidence | Action |
| Zone 1-Full Autonomy | Low-risk, low-complexity, high confidence. | The agents execute the task end-to-end with every action fully audited. |
| Zone 2- Autonomy with Active Monitoring | Moderate risk, task that is operationally complex (Example, tricky test data setups or UI-to-API boundary switches) | The platform executes the action while enhanced monitoring activates. |
| Zone 3- Structured Escalation | High risk, genuine ambiguity, or the platform’s confidence in its own knowledge drops. | The agents pause, ask one precise question, and resume on their own the moment it’s answered. Here escalation is a small interruption, not a dropped thread. |
| Zone 4- Human-Led, Platform-Supported | High risk and high complexity. | The platform doesn’t act independently. Instead, it hands the human everything relevant — context, precedent, risk dataand steps back. The final decision belongs to the human reviewer. |
QE Productivity and Value Impact Across Throughput, Quality, Efficiency, and Risk
One of the hardest to track metric in the AI age is its immediate impact on business outcomes. QE teams need more depth and insight than just measuring how much testing efforts AI platforms can take up. QMentisAI’s agentic QE is focused on outcomes that are more measurable and not arbitrary activity metrics to connect to more meaningful outcomes like customer experience, operational continuity, revenue protection, and brand trust.
Layer 1: Efficiency
Rather than arbitrary numbers on test automation coverage, QMentisAI helps measure:
- The actual % of test requirements analysed by the agents.
- The % of test cases generated.
- The % of automation candidates identified.
- Actual QE hours saved.
- Time spent on analyzing execution results.
- Human interventions needed/release.
- Autonomous actions/release.
Layer 2: Quality Intelligence
The platform helps measure the variables that are actually making QE better not just faster and impact your enterprise product quality:
- High-priority Product Risks:
- Risk-to-coverage ratio
- Change-impact prediction accuracy
- Residual-risk identification accuracy
- Likelihood of Defects Reaching Production:
- Requirement-to-test traceability
- Defect detection earlier in SDLC
- Escaped defect rate
- Improved Test Execution:
- Coverage gaps identified before execution
- False-positive rate
- QE Efficiency & Responsiveness
- Defect triage time
Layer 3: Agent Trust
This is where QMentisAI’s brand-new version differentiates with its architecture providing the foundation for self-monitoring of escalation drifts, correction clusters, stale knowledge, and over confidence. QE teams can track:
- Human override rate
- Escalation rate
- Correction frequency
- Knowledge freshness
- % of consequential decision with named accountability
Accountability: Where does the humans layer architecturally lives in QMentisAI?
Agent-powered doesn’t mean that QMentisAI is a replacement for QE judgment. The goal is to build more human judgment per unit of engineering effort. Therefore, the platform explicitly and architecturally scales and amplifies human oversight. The human accountability resides at five distinctive points:
- Within The Autonomy Zone Itself: In the zone 3 and 4 as permanent categories in the decision architecture human accountability is engineered in right from the outset for situations where human reviewers and experts must own the decision.
- Dedicated Human Judgment layer: Every time the platform escalates, it follows three standards: it must be understandable in under sixty seconds, it must arrive with everything needed to decide without leaving the platform, and the human’s answer has to be captured with enough fidelity to teach the system something. This is an engineered interface, not an informal “ask a person” step.
- Four Collaboration Moments Across the Actual Workflow: Right from the requirement entering or dynamically evolving, accumulated risk crossing a threshold, test execution revealing a release-consequential pattern, and readiness at every handoff. At each of these phases, the platform proactively briefs three roles at once —QE lead, engineering lead, product manager with each personnel getting a view calibrated to their own decision.
- The Override Architecture: Every consequential autonomous action maps to an explicit human decision by design. Any authorized person can override autonomous operation at any point, and that right is permanent and prominently placed, it is not something a person has to go looking for in a settings menu.
Conclusion
For a Head of QE running quality across billion-dollar, customer-facing operations, with agentic-driven QE powered by platforms like QMentisAI: how much confidence has become your expertise when signing of a release will stop being a rhetorical question. It will remain an operational requirement where the six-phase agentic layer, four-zone autonomy, and human accountability layers will address the underlying QE demands that a traditional automation or generic AI-powered testing tool cannot cater to. Your QE function will eventually transform into a quality engine that can answer in a moment, what was tested and who signed off the judgement. That’s the real difference between a hope and evidence.
This was the first part, unpacking what QualiZeal’s governed agentic QE actually does. In the part 2 of this series, we go deeper into the trust architecture of QMentisAI. Stay tuned.
Ready to see what evidence looks like your own release data? Our experts are glad to connect and schedule a demo!